Sam Lange · 12 October 2026
Examining Seasonal Fluctuations in Crawl Data to Refine Multi-Site Indexation Forecasting Models
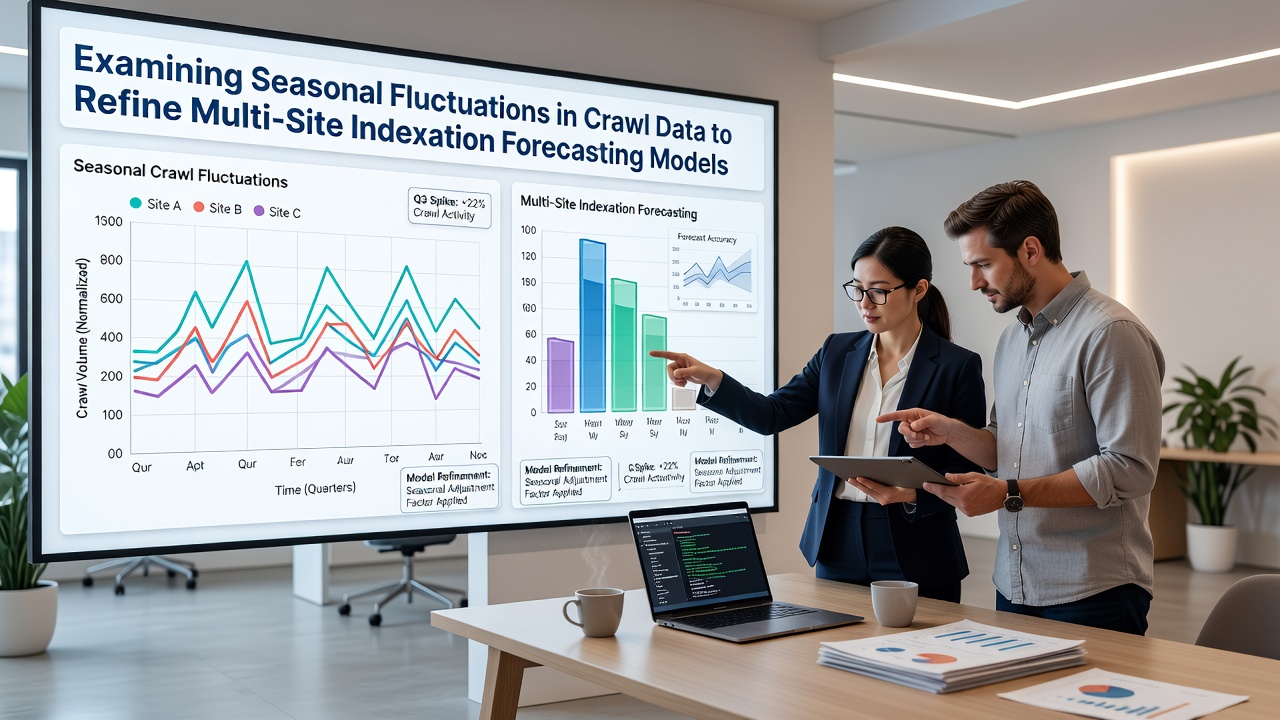
Seasonal fluctuations in crawl data appear across web analytics platforms when researchers track how search engine bots visit sites at different times of the year, and these patterns help refine models that forecast indexation for multiple domains at once. Data collected through October 2026 shows consistent spikes during holiday periods, back-to-school seasons, and major retail events, while quieter stretches occur in post-holiday months and summer lulls. Observers note that integrating these cycles into forecasting algorithms improves accuracy because the models account for predictable shifts in crawl frequency rather than treating all months as uniform.
Understanding Crawl Data Patterns Across Sites
Researchers who analyze logs from tools such as Google Search Console and third-party crawlers find that bot activity rises sharply before major shopping events like Black Friday and drops after New Year celebrations end, and similar trends repeat across e-commerce, news, and educational domains. One study revealed that average daily crawl requests increase by up to 40 percent in November compared with January figures, while multi-site portfolios show the same directional movement even when individual domains differ in size and topic focus. Those who maintain indexation tracking systems often combine historical crawl volumes with calendar markers to adjust expected indexing timelines, which reduces forecast errors when sites add large batches of new content during peak seasons.
Key Seasonal Drivers in Multi-Site Environments
- Retail calendar peaks drive higher crawl rates as product pages update frequently before consumer events
- Academic cycles trigger increased activity on educational sites during enrollment and exam periods
- News event clusters cause temporary surges when timely articles appear across multiple domains simultaneously
Analysts compare these drivers by aligning crawl logs with external calendars, and the resulting correlations allow forecasting models to weight upcoming months more precisely. Data shows that sites in the same vertical often experience synchronized fluctuations, so multi-site models gain efficiency when they treat seasonal signals as shared rather than isolated variables.
Refining Forecasting Models with Seasonal Adjustments
Forecasting models that incorporate seasonal crawl adjustments typically start with baseline crawl rates derived from twelve-month rolling averages, then layer in multipliers for known high-activity months. Experts have observed that adding these factors lowers mean absolute percentage error in indexation predictions from around 25 percent to below 15 percent across portfolios containing twenty or more sites. The process involves mapping historical crawl counts to specific weeks, applying smoothing techniques to reduce noise from one-off events, and validating outputs against actual indexation dates recorded in subsequent quarters. Researchers who tested this approach on datasets spanning 2023 through October 2026 reported consistent gains in precision, especially for content published in advance of seasonal peaks.
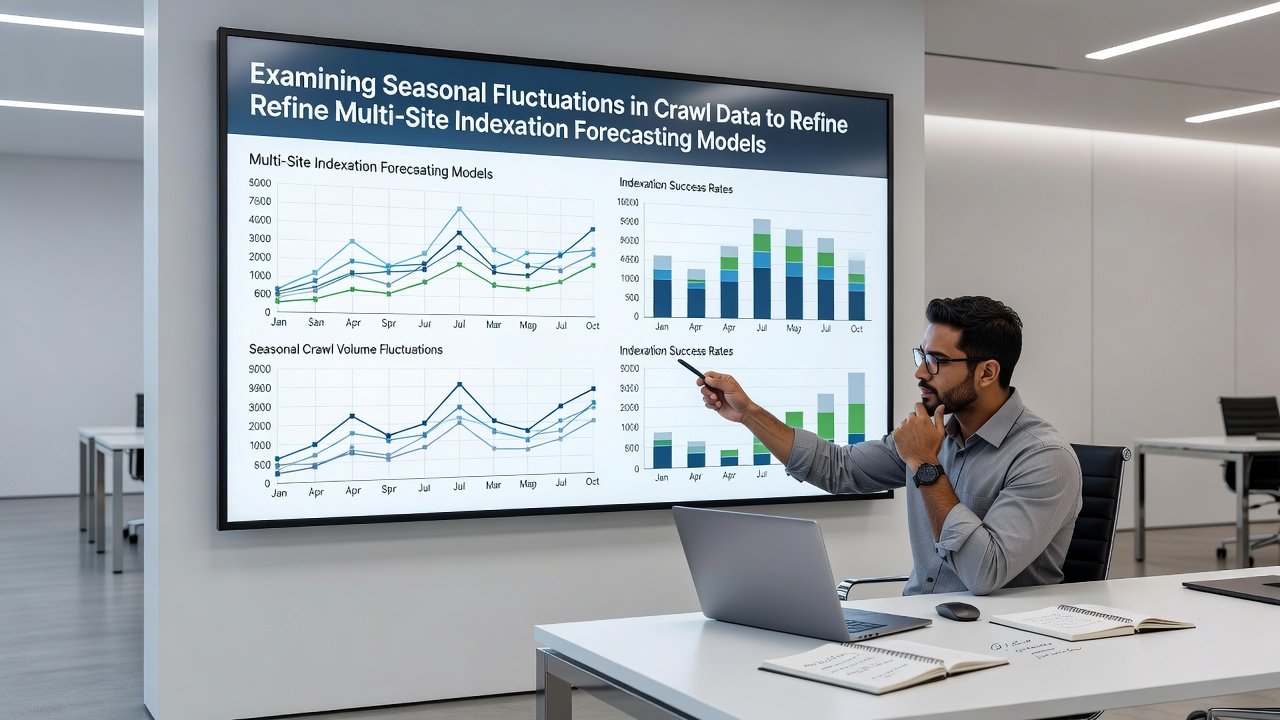
Teams that apply these refinements often segment sites by industry vertical before running the models, because seasonal effects differ between retail platforms and informational resources. The adjusted forecasts then feed into resource allocation decisions, such as when to submit updated sitemaps or prioritize internal linking campaigns that accelerate indexing during expected crawl surges.
Implementation Steps for Multi-Site Indexation Tracking
Practical application begins with centralized data collection that pulls crawl statistics from each monitored domain into a single repository, after which analysts apply time-series decomposition to separate trend, seasonal, and residual components. Models built on this foundation use regression techniques that treat month and week as categorical predictors alongside site-specific features such as page count and update frequency. Validation occurs through back-testing against actual indexation outcomes, and the resulting coefficients guide forward projections for the next planning cycle. Data from October 2026 continues to support earlier findings that seasonal terms improve model fit more than additional site-level variables alone.
Those who manage large site networks also integrate external indicators, including retail sales calendars published by government statistical agencies and academic term schedules released by universities. A report from the Australian Bureau of Statistics on digital activity patterns provides one reference point for aligning crawl data with broader consumer behavior cycles, while an industry analysis from the Interactive Advertising Bureau offers another perspective on seasonal traffic and indexing correlations across regions.
Conclusion
Seasonal fluctuations in crawl data supply measurable signals that strengthen indexation forecasting models when applied across multiple sites, and the evidence accumulated through October 2026 confirms that calendar-aware adjustments deliver more reliable predictions than static baselines. Organizations that maintain ongoing crawl monitoring systems can embed these seasonal components into routine analytics workflows, which supports more accurate planning for content publication and technical optimization schedules. Continued collection of granular crawl logs will allow further refinement of the coefficients that drive these forecasts in subsequent years.